
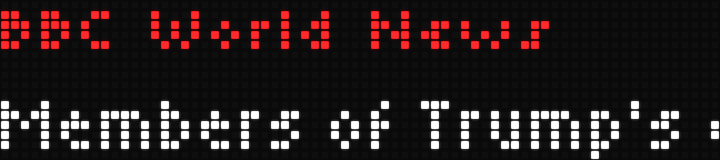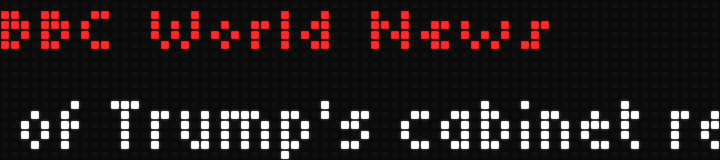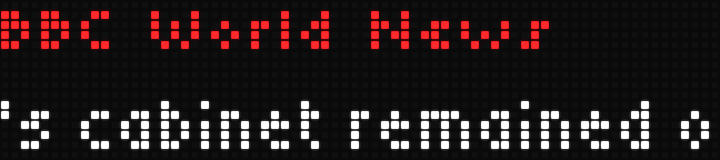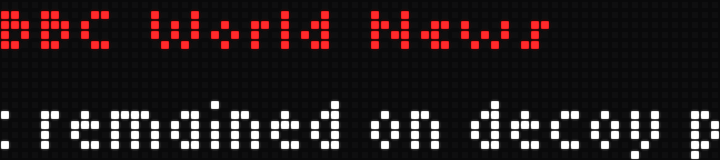
RSS Feed Scroller
Fetch an RSS feed and show it
How to run
This app is a single Python file that talks directly to the BUSY Bar HTTP API: no libraries, no setup. Connect your bar via USB and run:
python app.py
Over USB the bar is always at 10.0.4.20. On Wi-Fi, pass the bar's IP
with --host <address>.
No bar at hand? Run the
BUSY Bar Emulator
and point the app at it: python app.py --host 127.0.0.1:8080.
To keep it running without a terminal open, install it with busybar-manager, which handles the virtualenv, autostart and scheduling, and lets you switch between apps from a web dashboard.
Source code
app.py
#!/usr/bin/env python3
"""Multi-feed RSS/Atom scroller for BUSY Bar.

Downloads multiple feeds locally on the PC, keeps the feed name fixed on the
top row, scrolls its headlines on the bottom row, and rotates between feeds.

Examples:
    python3 rss-scroller.py
    python3 rss-scroller.py \
      --feed "NBC Top News=https://feeds.nbcnews.com/nbcnews/public/news" \
      --feed "BBC World News=https://feeds.bbci.co.uk/news/rss.xml"
    python3 rss-scroller.py --feed-seconds 20 --refresh 300
    python3 rss-scroller.py --font small --color "#FFFFFFFF"
    python3 rss-scroller.py --title-font tiny --title-color "#888888FF"
    python3 rss-scroller.py --host 127.0.0.1:8080
"""

import argparse
import html
import json
import re
import time
import unicodedata
import urllib.error
import urllib.parse
import urllib.request
import xml.etree.ElementTree as ET

APP = "rss-scroller"

DEFAULT_HOST = "10.0.4.20"
DEFAULT_FEEDS = [
    ("BBC World News", "https://feeds.bbci.co.uk/news/world/rss.xml"),
    ("NBC Top News", "https://feeds.nbcnews.com/nbcnews/public/news"),
    ("The Guardian World", "https://www.theguardian.com/world/rss"),
]
DEFAULT_REFRESH_SEC = 300
DEFAULT_FEED_SECONDS = 60
DEFAULT_MAX_ITEMS = 15
DEFAULT_MAX_TICKER_CHARS = 500
DEFAULT_SCROLL_RATE = 1000
DEFAULT_COLOR = "#FFFFFFFF"
DEFAULT_TITLE_COLOR = "#FF0000FF"
DEFAULT_SEPARATOR = " | "
DEFAULT_FONT = "small"
DEFAULT_TITLE_FONT = "tiny"

VALID_FONTS = (
    "tiny", "small", "normal", "condensed",
    "bold", "large", "extra_large", "global",
)

DISPLAY_WIDTH = 72
TITLE_Y = 0
TICKER_Y = 8
TICKER_CENTER_Y = 5

SCROLL_START_DELAY_MS = 300
SCROLL_REPEAT_DELAY_MS = 700

USER_AGENT = "busy-bar-rss-scroller/2.0"


def valid_color(value):
    if not re.fullmatch(r"#[0-9A-Fa-f]{8}", value):
        raise argparse.ArgumentTypeError(
            "color must use #RRGGBBAA format, for example #FF0000FF"
        )
    return value.upper()


def parse_feed_arg(value):
    """Parse NAME=URL. If no name is given, derive one from the hostname."""
    value = value.strip()
    if "=" in value:
        name, url = value.split("=", 1)
        name = name.strip()
        url = url.strip()
    else:
        url = value
        host = urllib.parse.urlparse(url).netloc
        name = host.split(":", 1)[0].replace("www.", "") or "RSS"

    if not name:
        raise argparse.ArgumentTypeError("feed name cannot be empty")
    if not url.startswith(("http://", "https://")):
        raise argparse.ArgumentTypeError("feed URL must start with http:// or https://")
    return name, url


def parse_args():
    p = argparse.ArgumentParser(description="Multi-feed RSS/Atom scroller for BUSY Bar")
    p.add_argument("--host", default=DEFAULT_HOST,
                   help=f"BUSY Bar host (default: {DEFAULT_HOST})")
    p.add_argument("--feed", action="append", type=parse_feed_arg,
                   metavar="FEED",
                   help="RSS/Atom feed as NAME=URL; repeat for multiple feeds")
    p.add_argument("--refresh", type=int, default=DEFAULT_REFRESH_SEC,
                   help=f"seconds between RSS refreshes (default: {DEFAULT_REFRESH_SEC})")
    p.add_argument("--feed-seconds", type=int, default=DEFAULT_FEED_SECONDS,
                   help=f"seconds each feed stays on screen (default: {DEFAULT_FEED_SECONDS})")
    p.add_argument("--max-items", type=int, default=DEFAULT_MAX_ITEMS,
                   help=f"maximum headlines per feed (default: {DEFAULT_MAX_ITEMS})")
    p.add_argument("--max-ticker-chars", type=int, default=DEFAULT_MAX_TICKER_CHARS,
                   help=f"maximum ticker text length (default: {DEFAULT_MAX_TICKER_CHARS})")
    p.add_argument("--scroll-rate", type=int, default=DEFAULT_SCROLL_RATE,
                   help=f"ticker scroll rate in pixels/minute (default: {DEFAULT_SCROLL_RATE})")
    p.add_argument("--font", choices=VALID_FONTS, default=DEFAULT_FONT,
                   help=f"ticker font (default: {DEFAULT_FONT})")
    p.add_argument("--title-font", choices=VALID_FONTS, default=DEFAULT_TITLE_FONT,
                   help=f"feed-name font (default: {DEFAULT_TITLE_FONT})")
    p.add_argument("--color", type=valid_color, default=DEFAULT_COLOR,
                   help=f"ticker color in #RRGGBBAA (default: {DEFAULT_COLOR})")
    p.add_argument("--title-color", type=valid_color, default=DEFAULT_TITLE_COLOR,
                   help=f"feed-name color in #RRGGBBAA (default: {DEFAULT_TITLE_COLOR})")
    p.add_argument("--hide-title", action="store_true",
                   help="hide the feed name and vertically center the scrolling ticker")
    p.add_argument("--separator", default=DEFAULT_SEPARATOR,
                   help="separator between headlines")
    p.add_argument("--timeout", type=float, default=10.0,
                   help="HTTP timeout for RSS and BUSY Bar calls")
    p.add_argument("--debug", action="store_true",
                   help="print BUSY Bar draw payload and ticker length")
    return p.parse_args()


def normalize_host(host):
    host = host.strip().rstrip("/")
    if host.startswith(("http://", "https://")):
        return host
    return "http://" + host


def clean_text(value):
    """Clean feed text and normalize common Unicode punctuation for BUSY Bar."""
    if not value:
        return ""

    value = html.unescape(value)
    value = re.sub(r"<[^>]+>", " ", value)

    replacements = {
        "\u2018": "'", "\u2019": "'", "\u201a": "'",
        "\u201c": '"', "\u201d": '"', "\u201e": '"',
        "\u2013": "-", "\u2014": "-", "\u2212": "-",
        "\u2026": "...",
        "\u00a0": " ",
        "\u2022": "*",
    }
    for src_ch, dst_ch in replacements.items():
        value = value.replace(src_ch, dst_ch)

    # Strip accents and any remaining non-ASCII code points. BUSY Bar's text
    # endpoint appears to reject some UTF-8 punctuation even when the JSON body
    # itself is valid.
    value = unicodedata.normalize("NFKD", value)
    value = value.encode("ascii", "ignore").decode("ascii")

    value = re.sub(r"\s+", " ", value).strip()
    return value


def _local_name(tag):
    if "}" in tag:
        return tag.split("}", 1)[1]
    return tag


def _first_child_text(node, names):
    wanted = set(names)
    for child in node.iter():
        if _local_name(child.tag).lower() in wanted:
            text = clean_text("".join(child.itertext()))
            if text:
                return text
    return ""


def fetch_feed(url, timeout=10.0):
    req = urllib.request.Request(
        url,
        headers={
            "User-Agent": USER_AGENT,
            "Accept": "application/rss+xml, application/atom+xml, application/xml, text/xml, */*",
        },
    )
    with urllib.request.urlopen(req, timeout=timeout) as resp:
        payload = resp.read()

    root = ET.fromstring(payload)
    root_name = _local_name(root.tag).lower()
    items = []

    if root_name == "feed":
        for entry in root:
            if _local_name(entry.tag).lower() != "entry":
                continue
            title = _first_child_text(entry, {"title"})
            link = ""
            for child in entry:
                if _local_name(child.tag).lower() == "link":
                    rel = child.attrib.get("rel", "alternate")
                    href = child.attrib.get("href", "")
                    if href and rel in ("alternate", ""):
                        link = href
                        break
            if title:
                items.append({"title": title, "link": link})
    else:
        for node in root.iter():
            if _local_name(node.tag).lower() != "item":
                continue
            title = _first_child_text(node, {"title"})
            link = _first_child_text(node, {"link"})
            if title:
                items.append({"title": title, "link": link})

    return items


def dedupe_items(items):
    seen = set()
    out = []
    for item in items:
        key = (item.get("link") or item.get("title") or "").strip().lower()
        if not key or key in seen:
            continue
        seen.add(key)
        out.append(item)
    return out


def build_ticker(items, max_items, separator, max_chars):
    """Build a ticker without exceeding max_chars, preserving whole headlines."""
    titles = []
    current_len = 0

    for item in items[:max_items]:
        title = clean_text(item.get("title", ""))
        if not title:
            continue

        extra = len(title) if not titles else len(separator) + len(title)

        # Always allow at least one headline. If the first headline alone is too
        # long, trim it safely instead of returning an empty ticker.
        if not titles and len(title) > max_chars:
            return title[:max_chars].rstrip()

        if current_len + extra > max_chars:
            break

        titles.append(title)
        current_len += extra

    return separator.join(titles)


def _request(base, path, *, method="GET", data=None, headers=None, timeout=5):
    req = urllib.request.Request(
        base + path,
        data=data,
        method=method,
        headers=headers or {},
    )
    return urllib.request.urlopen(req, timeout=timeout)


def draw_feed(base, feed_name, ticker, args):
    ticker_y = TICKER_CENTER_Y if args.hide_title else TICKER_Y

    elements = []

    if not args.hide_title:
        elements.append({
            "id": "feed_name",
            "type": "text",
            "text": feed_name,
            "x": 0,
            "y": TITLE_Y,
            "font": args.title_font,
            "color": args.title_color,
            "align": "top_left",
        })

    elements.append({
        "id": "rss",
        "type": "text",
        "text": ticker,
        "x": 0,
        "y": ticker_y,
        "font": args.font,
        "color": args.color,
        "align": "top_left",
        "width": DISPLAY_WIDTH,
        "scroll_rate": args.scroll_rate,
        "scroll_start_delay": SCROLL_START_DELAY_MS,
        "scroll_repeat_delay": SCROLL_REPEAT_DELAY_MS,
    })

    body = {
        "application_name": APP,
        "priority": 30,
        "elements": elements,
    }

    data = json.dumps(body).encode("utf-8")
    if args.debug:
        print(f"[debug] ticker chars: {len(ticker)}")
        print(f"[debug] title hidden: {args.hide_title}")
        print(f"[debug] ticker y: {ticker_y}")
        print("[debug] draw payload:")
        print(json.dumps(body, ensure_ascii=False, indent=2))
    try:
        with _request(
            base,
            "/api/display/draw",
            method="POST",
            data=data,
            headers={"Content-Type": "application/json"},
            timeout=args.timeout,
        ):
            return True
    except urllib.error.HTTPError as e:
        if e.code == 409:
            print("[busy] display occupied by a higher-priority app")
            return False
        detail = e.read().decode("utf-8", "ignore")
        raise RuntimeError(f"BUSY Bar HTTP {e.code}: {detail}") from e
    except urllib.error.URLError as e:
        raise RuntimeError(f"cannot reach BUSY Bar at {base}: {e.reason}") from e


def clear_display(base, timeout):
    query = urllib.parse.urlencode({"application_name": APP})
    try:
        with _request(
            base,
            "/api/display/draw?" + query,
            method="DELETE",
            timeout=timeout,
        ):
            pass
    except Exception:
        pass


def refresh_all_feeds(feed_defs, cache, timeout):
    for name, url in feed_defs:
        try:
            items = dedupe_items(fetch_feed(url, timeout=timeout))
            if items:
                cache[name] = items
                print(f"[rss] {name}: fetched {len(items)} item(s)")
            else:
                print(f"[rss] {name}: no usable items")
        except Exception as e:
            print(f"[rss] {name}: fetch failed: {e}")
            if name in cache:
                print(f"[rss] {name}: keeping last valid headlines")


def main():
    args = parse_args()
    base = normalize_host(args.host)

    feed_defs = args.feed if args.feed else list(DEFAULT_FEEDS)
    refresh_sec = max(10, args.refresh)
    feed_seconds = max(5, args.feed_seconds)
    max_items = max(1, args.max_items)
    max_ticker_chars = max(64, args.max_ticker_chars)

    print(f"rss-scroller -> {base}")
    print(f"feeds: {len(feed_defs)}")
    for name, url in feed_defs:
        print(f"  - {name}: {url}")
    print(
        f"refresh: {refresh_sec}s | feed seconds: {feed_seconds}s | "
        f"scroll rate: {args.scroll_rate} | title font: {args.title_font} | "
        f"ticker font: {args.font} | max ticker chars: {max_ticker_chars} | "
        f"title: {'hidden' if args.hide_title else 'visible'}"
    )
    print("Ctrl-C to stop.")

    cache = {}
    last_refresh = 0.0
    current_index = 0

    try:
        while True:
            now = time.monotonic()

            if last_refresh == 0.0 or now - last_refresh >= refresh_sec:
                refresh_all_feeds(feed_defs, cache, args.timeout)
                last_refresh = time.monotonic()

            name, _url = feed_defs[current_index]
            items = cache.get(name, [])
            ticker = build_ticker(items, max_items, args.separator, max_ticker_chars)

            if ticker:
                try:
                    if draw_feed(base, name, ticker, args):
                        print(f"[busy] showing {name}")
                except Exception as e:
                    print(f"[busy] draw failed: {e}")
            else:
                print(f"[busy] {name}: nothing to display")

            # Keep this feed visible, but wake periodically so a refresh can
            # happen on schedule even during a long feed dwell time.
            shown_at = time.monotonic()
            while time.monotonic() - shown_at < feed_seconds:
                time.sleep(1)
                now = time.monotonic()
                if now - last_refresh >= refresh_sec:
                    refresh_all_feeds(feed_defs, cache, args.timeout)
                    last_refresh = time.monotonic()

            current_index = (current_index + 1) % len(feed_defs)

    except KeyboardInterrupt:
        print("\nstopped.")
    finally:
        clear_display(base, args.timeout)


if __name__ == "__main__":
    main()